
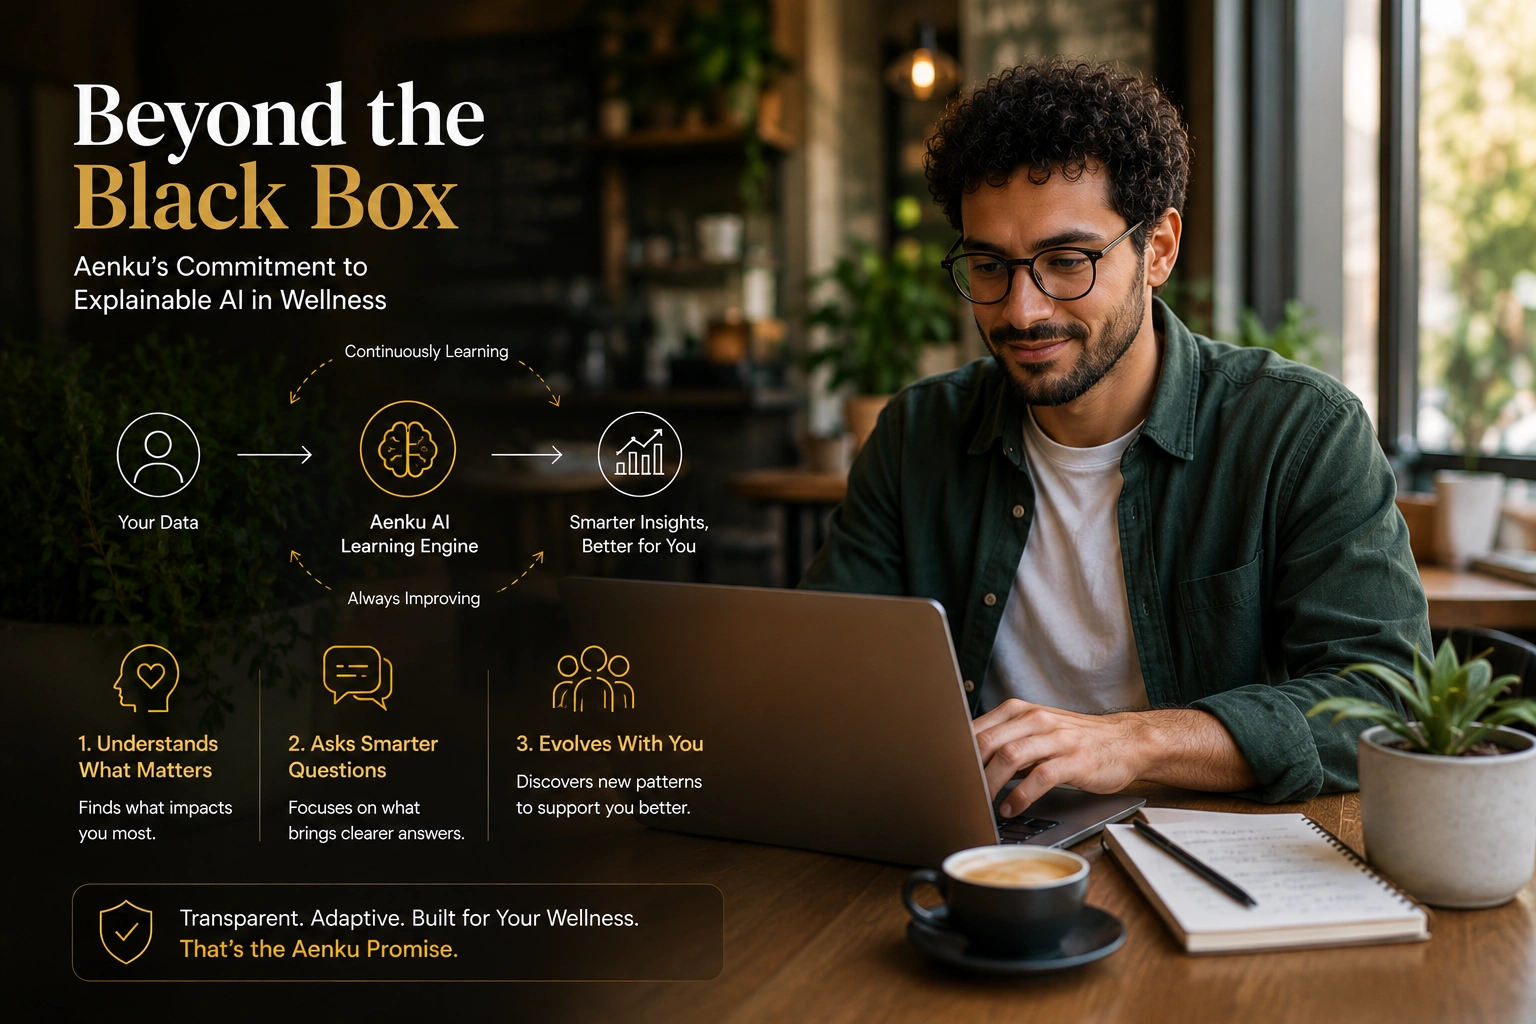
Beyond the black box Explainable AI In Wellness Aenku · Showing its work
There is a version of AI-powered wellness that tells you what to do, declines to explain why, and expects you to trust the output because it came from an algorithm. That version is everywhere.
Aenku was built on a different premise. Every recommendation the engine makes comes with a complete rationale: the primary driver, the ranked signals that contributed, the confidence level, the risk flags specific to your profile, and a transparent accounting of which data was used and which was not. Not as an afterthought, as the core feature.
Here is how the engine actually works, in plain language, with nothing held back.
The Problem With
Black Box Wellness
When an AI system gives you a recommendation without explaining it, something important is missing. Not just transparency, though that matters. What is missing is your ability to push back, to calibrate, to use the recommendation intelligently rather than just comply with it or ignore it.
A coffee timing suggestion that comes with a number but no reason is not more powerful than one that comes with a clear rationale. It is less powerful, because you have no way to know whether the reason applies to your situation today, or whether a variable it does not know about changes the answer entirely.
A recommendation you understand is one you can act on with conviction. A recommendation you cannot understand is one you follow blindly or ignore completely. Aenku is built for the first kind of relationship.
Aenku Design Principles · Explainability FirstThe Aenku Wellness Engine is built around a class called AENKU_Explainability that runs alongside every recommendation. It does not produce the recommendation. It explains it. The two processes are separate by design, because the explanation is not a feature layered on top of the output. It is a parallel output with equal standing.
What You Actually
See in the App
Before the engine internals, here is the thing that matters most: what a real recommendation looks like to a real user on a real morning, with full explainability active. Every element below is generated, not templated.
That last element is worth pausing on. The transparency note does not only list what data was used. It lists what data was not available. You can see exactly where the engine's knowledge ends and where its best estimate begins.
How Signals Are
Ranked and Weighted
Behind every recommendation is a ranked list of contributing signals. The extract_signals() method identifies and scores every relevant data point in your profile against the candidate recommendation. The highest-scoring signals become your explanation. The lower-scoring ones are recorded but do not dominate the output.
Domain Weights:
What the Engine Prioritizes
Not every wellness domain is equally useful for distinguishing between different user types. The learn_domain_weights() method continuously measures which domains produce the highest variation across persona types. High variation means a domain is discriminative: it reliably separates one kind of user from another. These domains get elevated weight in subsequent scoring.
Sleep and stress consistently emerge as the most discriminative domains across user populations. This makes biological sense: your sleep quality on any given night and your baseline stress load are the two variables that most reliably predict whether caffeine will work for or against you on that specific day. The engine weights its calculations accordingly.
The Learning Loop:
How the Engine Gets Smarter
The engine does not operate on a fixed model. It runs a continuous retraining cycle that updates its understanding of domain weights, question effectiveness, and persona boundaries each time a threshold of new user submissions arrives. This happens asynchronously, meaning it never interrupts your experience.
Emerging Segments:
The Personas That Did Not Exist Yet
When the engine was first built, it knew twelve persona archetypes. It does not assume those twelve are permanent or complete. The detect_emerging_segments() method runs after every retraining cycle looking for clusters of users who consistently fall outside the existing taxonomy.
When a new segment accumulates enough users to be statistically meaningful, the engine proposes a new persona archetype. This is the mechanism by which Aenku's understanding of human wellness expands rather than remaining frozen at whatever was known when the system launched.
Why Transparency
Is the Product
There is a practical argument for explainability beyond the ethical one. When users understand why a recommendation was made, they engage with it more thoughtfully. They notice when a variable the engine did not know about changes the situation. They provide better feedback. That feedback enters the learning loop. The model improves. The next recommendation is better.
Transparent recommendation leads to informed user engagement. Informed engagement produces richer feedback signals. Richer feedback improves the model's accuracy. Better accuracy leads to recommendations users trust and act on. Actions produce outcomes. Outcomes generate data. That data enters the next retraining cycle.
Every user who interacts thoughtfully with an Aenku explanation rather than simply following or ignoring the output contributes to making the engine more accurate for the next person with a similar profile. This is what it means when we say the system learns collectively: not that your private data is shared, but that the patterns your behavior reveals about which signals matter most become part of what the engine knows how to look for.
See the engine explain
a recommendation for you
The full Aenku Coffee Wellness Assessment at aenku.com does not just produce a protocol. It shows you every reason, every signal, every risk flag, and every data gap that went into it. You will understand your biology and your coffee differently after the first result.
Questions About the Engine
What is Explainable AI and why does Aenku use it?
Explainable AI means the system can describe in plain language exactly why it made a specific recommendation. Aenku uses it because a wellness recommendation you do not understand is one you cannot meaningfully act on. Every Aenku output includes a top reason, ranked signals, contributing factors, risk warnings, a confidence score, and a transparent list of data sources used and not used. You know why before you decide whether to follow it.
How does Aenku's AI learn over time?
The Aenku Learning Engine runs an asynchronous retraining loop triggered after a threshold of new user submissions. It learns domain weights by identifying which wellness areas best distinguish between persona types, re-ranks questions based on how discriminative they prove to be in practice, and actively scans for emerging user segments that do not fit existing persona archetypes. Each user contributes to making the engine smarter for everyone who follows.
What does the confidence score actually mean?
The confidence score reflects how much high-quality data the engine had available when generating your recommendation. A high score means multiple data sources aligned clearly. A lower score means the engine had limited information and is making its best estimate with what was available. The score helps you calibrate how closely to follow the recommendation versus treating it as a useful starting point that benefits from more connected data.
Does Aenku change recommendations based on feedback I give it?
Yes. When you rate the energy quality after a cup or log how a timing change affected your afternoon, that feedback enters the learning loop directly. The engine refines its understanding of which signals are most predictive for your profile specifically. Over time the recommendations become increasingly tuned to you as an individual rather than as a member of a persona category.
The era of AI systems that ask for your trust without offering reasons in return is ending, not because people suddenly became more skeptical, but because they have started to notice that unexplained recommendations are not actually more authoritative. They are just less useful.
Aenku was built during that transition and built on the right side of it. Every signal the engine considers, every weight it applies, every confidence score it outputs, and every warning it surfaces is visible to you. Not as a technical readout. As a plain-language explanation of a decision that affects your morning, your focus, and your sleep.
The black box is not more intelligent. It is just less honest. And at aenku.com, honesty about how the machine thinks is part of what makes the machine worth trusting.

